Meet Ramu

A little AI that knows its home.

Chat with Gemma directly on Android. Follow your phone’s condition and understand your habits, with a familiar little companion.

Why choose local AI?
A home for your AI.
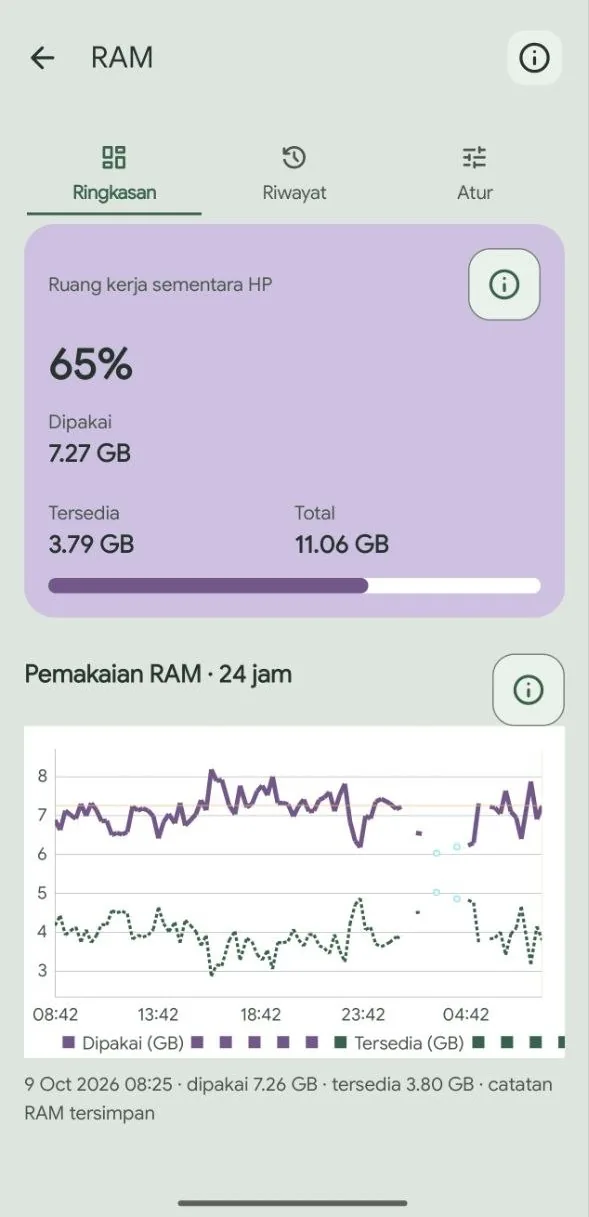
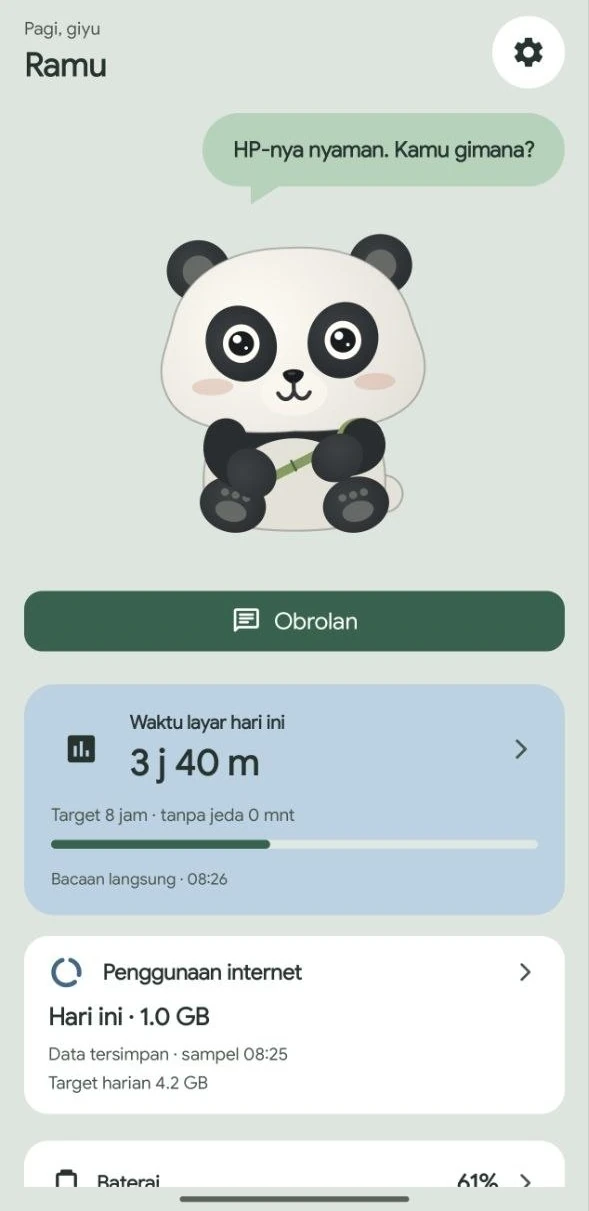
Ramu Home showing Bao, screen time, and internet usage
Chat · Monitor · Understand
Ramu on Android. Actual app capture.

From everyday conversations to the story behind your phone’s data.

  • Local AI chat
  • Phone status
  • Screen & data use

Features

Start a conversation. Find the pattern.

Choose a feature to see how Ramu helps.

Local AI, your way

Your choice of Gemma.

Choose a compatible E2B or E4B variant. Memory and storage needs differ between models.

Gemma 3nE2BGemma 3nE4B
Compare models
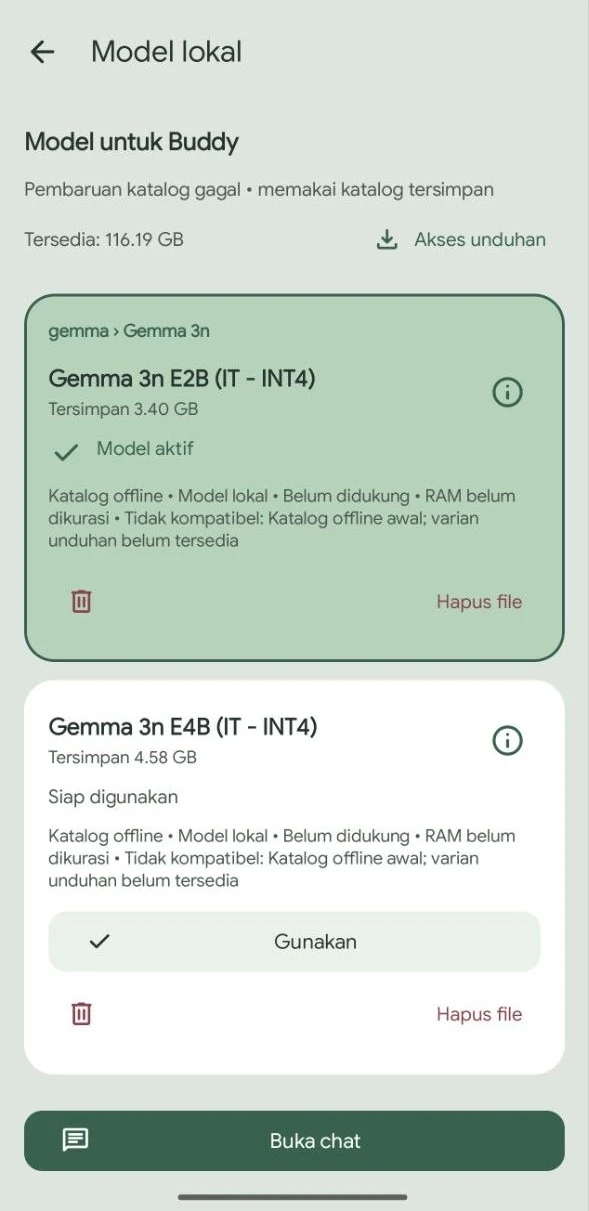
Ramu local model management screen showing installed Gemma models
Actual app capture

Local AI, your way

Shape the way it replies.

Adjust temperature, top-k, top-p, and response length. A system prompt guides the AI’s tone and role.

Example system promptKeep replies short. Explain phone data in plain language.
TemperatureTop-k / Top-pResponse length
Compare models
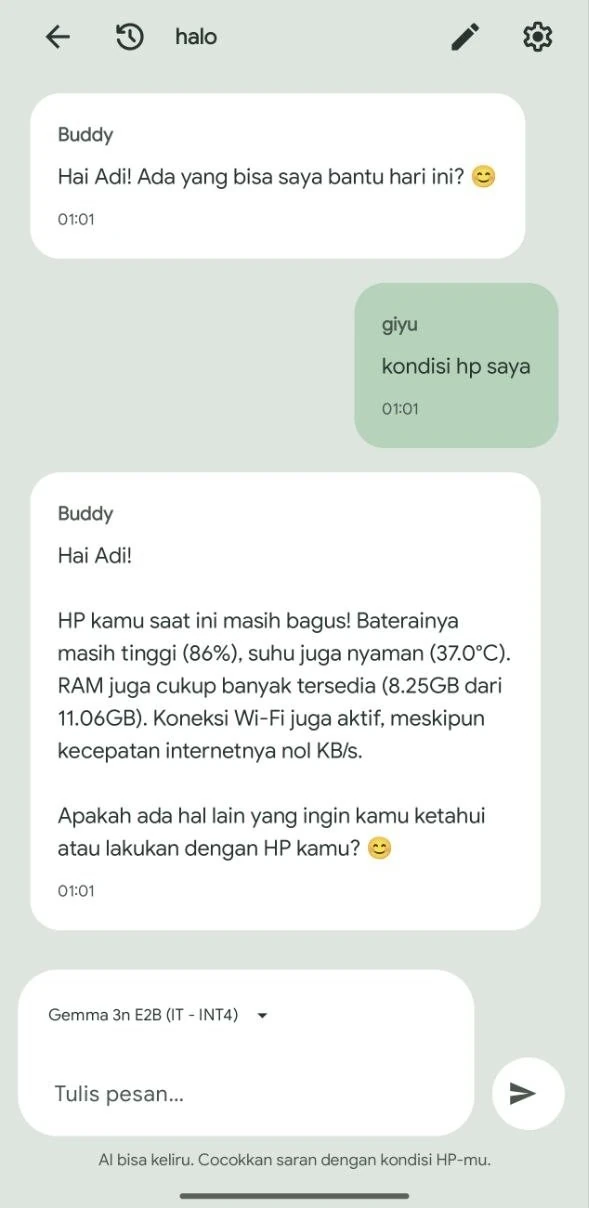
A conversation with Buddy in the Ramu Android app
Actual app capture

Local AI, your way

Ask about your phone.

Include saved monitoring data as context. Check the AI’s explanation against the original charts and records.

Saved readingsYour questionGemma
Compare models
A conversation with Buddy in the Ramu Android app
Actual app capture
1 / 3

Device monitoring

Know your phone better.

Phone warm or slowing down? Start with current readings, then trace when things changed.

Your phone, at a glance

Keep an eye on charge and heat.

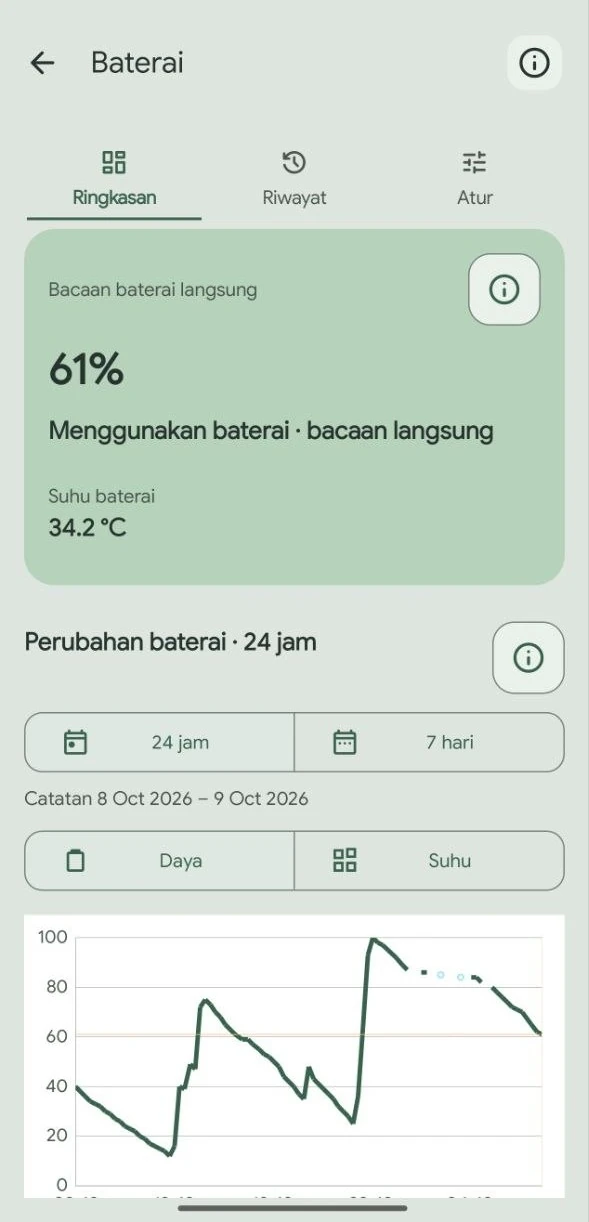
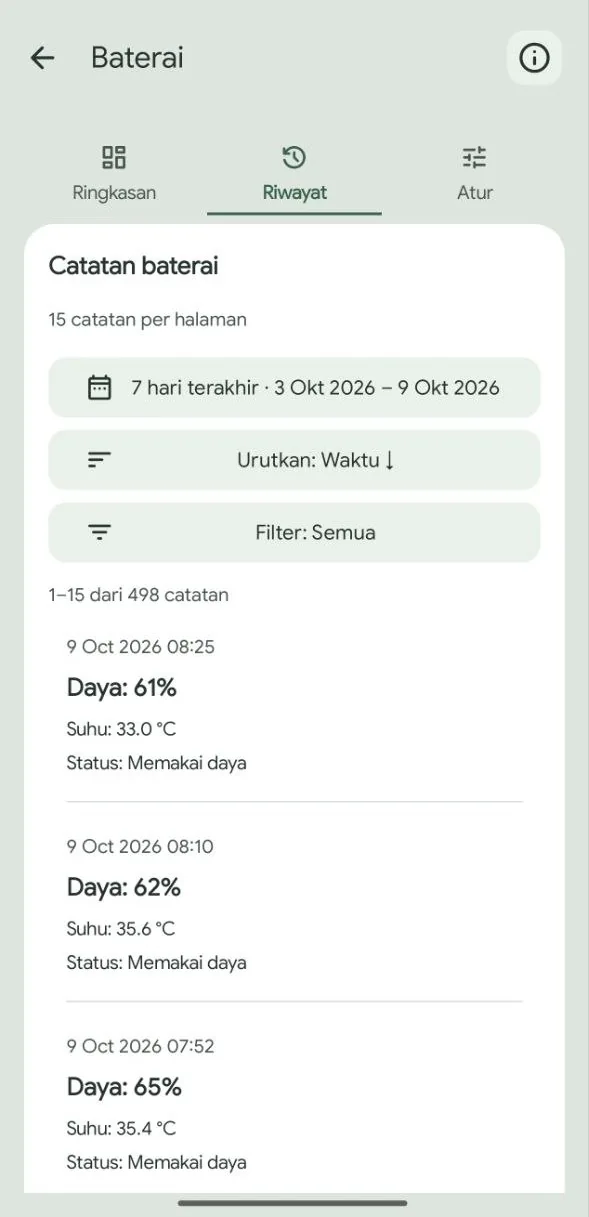
Check battery level and temperature, then trace changes through charts and charging records.

  • Current charge and temperature
  • Charts and charging history
Ramu Battery screen with level, temperature, and activity chart

Need a closer look? Open history or export monitoring and screen-time records as CSV for analysis.

Usage insights

Where do your time and data go?

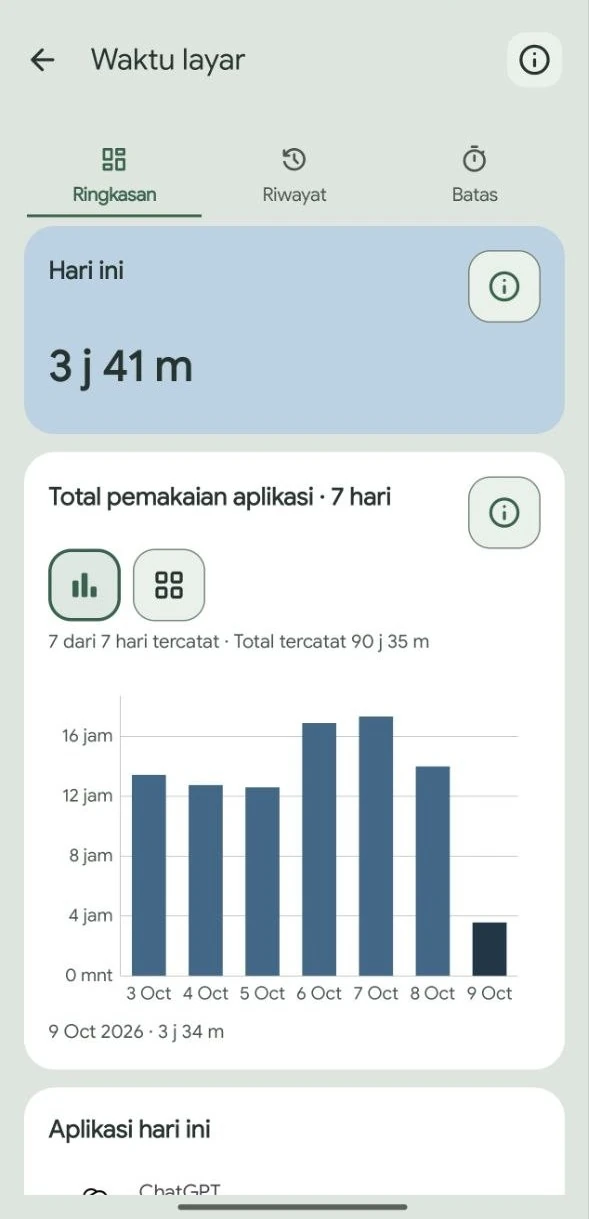
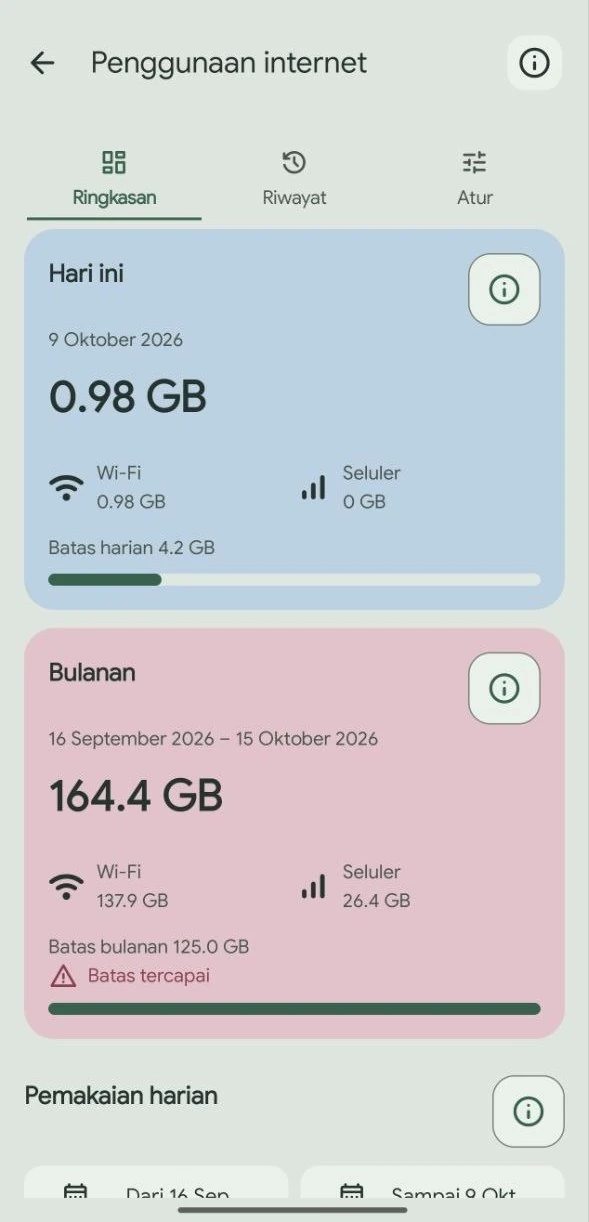
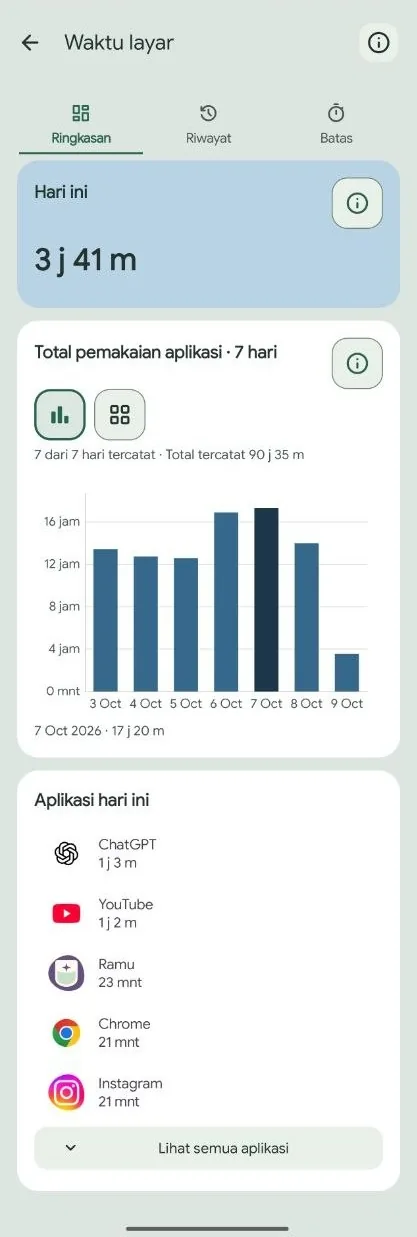
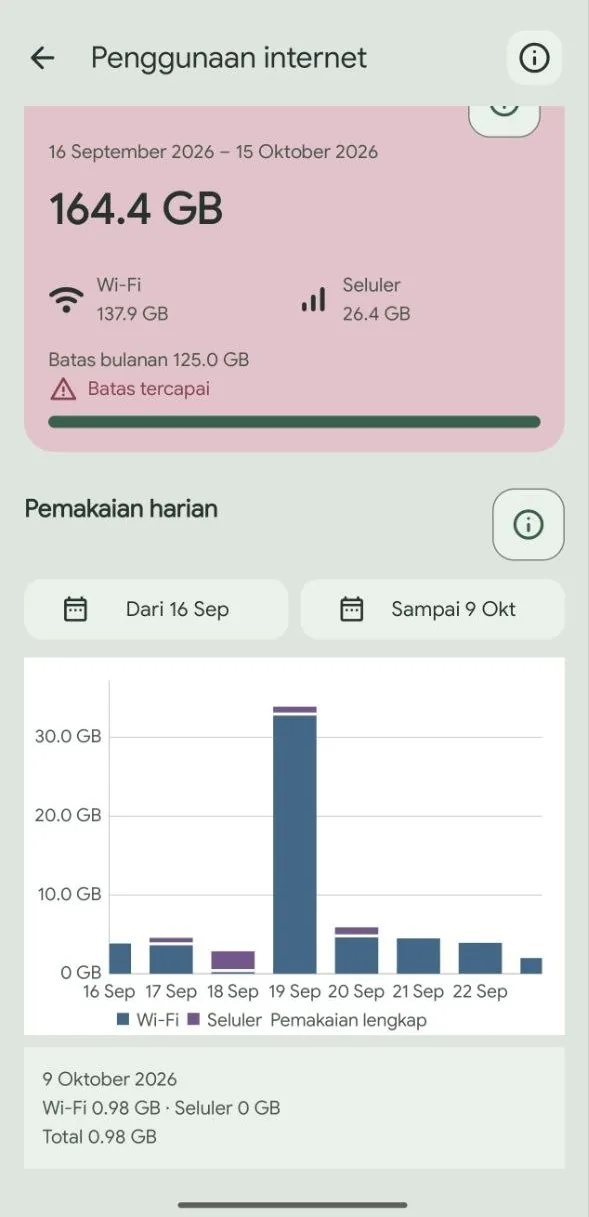
See which apps take your time and how Wi-Fi or mobile data adds up. Charts make daily patterns easier to spot.

Set personal limits

Set app time limits and daily or monthly data targets to fit your routine.

Ask AI about the pattern

Use saved data as context when asking Gemma. Check its explanation against the original charts.

Ramu Screen Time summary with an hourly usage chart
Screen TimeBy hour · by app
Ramu Internet Usage summary for Wi-Fi and mobile data
Internet UsageWi-Fi · mobile · billing cycle

Why local AI

Closer to you. More in your control.

Your questionGemmaRuns on your phoneA reply for you
Stays on your deviceNo AI server between question and answer.

The conversation stays on your phone.

Gemma processes your question on-device, without needing to send the prompt to an AI server.

No signal?Keep the conversation going.
Download and prepare a modelOnce a compatible model is ready, chat works offline.

No signal. Still a conversation.

Local chat works once a compatible model is ready. Downloads, updates, and network tests still need internet.

Local AI
Phone
Gemma
✓
Your phone does the work

RAM · battery · storage

Cloud AI
Phone
A server does the work

Internet · provider policies

Know where the work happens.

Local AI uses your phone’s resources. Cloud AI depends on a network and provider policies. The model and device affect results and speed.

1 / 3
What still matters

Local processing reduces the need to send data to an AI server. Device security, app permissions, and exported files still matter. AI can also make mistakes.

About Gemma on mobile

AI Models

Find your Gemma.

Compare variants, formats, and stored sizes. Compatibility and performance depend on your device.

2models listed

2 models shown

Gemma 3nListed in Ramu

Gemma 3n E2B (IT - INT4)

The E2B effective-parameter variant for local text conversations in Ramu.

Variant
E2B
Quantization
INT4
Model context
32K tokens
Observed stored size
≈3.40 GB
Runtime
LiteRT-LM
Model specifications
Model identifier
gemma-3n-e2b-it-int4
Family
Gemma 3n
Variant
E2B
Instruction tuning
IT
Quantization
INT4
Observed stored size
≈3.40 GB
Runtime
LiteRT-LM
Model format
.litertlm
Model context
32K tokens
Model input types
Text, Image, Audio
Creator
Google DeepMind
License
Gemma Terms of Use

Device requirements for this variant have not been validated. A listing does not guarantee that it will run on every phone.

These inputs describe Gemma 3n’s capabilities. Ramu currently uses text chat with an 8,192-token window.

Official model source
Gemma 3nListed in Ramu

Gemma 3n E4B (IT - INT4)

The E4B effective-parameter variant for local text conversations in Ramu.

Variant
E4B
Quantization
INT4
Model context
32K tokens
Observed stored size
≈4.58 GB
Runtime
LiteRT-LM
Model specifications
Model identifier
gemma-3n-e4b-it-int4
Family
Gemma 3n
Variant
E4B
Instruction tuning
IT
Quantization
INT4
Observed stored size
≈4.58 GB
Runtime
LiteRT-LM
Model format
.litertlm
Model context
32K tokens
Model input types
Text, Image, Audio
Creator
Google DeepMind
License
Gemma Terms of Use

Device requirements for this variant have not been validated. A listing does not guarantee that it will run on every phone.

These inputs describe Gemma 3n’s capabilities. Ramu currently uses text chat with an 8,192-token window.

Official model source
Understanding model specifications

32K is Gemma 3n’s model context capacity. Ramu currently uses an 8,192-token window and text chat. Image/audio inputs describe the model family, not Ramu’s current chat features. Stored size is not download size or RAM usage.

Gemma 3n documentation

Compare configurations

Select up to three models above.

Gemma 3n E2B (IT - INT4)

Family
Gemma 3n
Variant
E2B
Instruction tuning
IT
Quantization
INT4
Observed stored size
≈3.40 GB
Runtime
LiteRT-LM
Model format
.litertlm
Model context
32K tokens
Model input types
Text, Image, Audio
Creator
Google DeepMind
License
Gemma Terms of Use
Compatibility
Device requirements unverified

Gemma 3n E4B (IT - INT4)

Family
Gemma 3n
Variant
E4B
Instruction tuning
IT
Quantization
INT4
Observed stored size
≈4.58 GB
Runtime
LiteRT-LM
Model format
.litertlm
Model context
32K tokens
Model input types
Text, Image, Audio
Creator
Google DeepMind
License
Gemma Terms of Use
Compatibility
Device requirements unverified

Our story

It started with a little curiosity.

Ramu began as an experiment running Gemma directly on Android. It grew into a companion for conversations and understanding your phone.

Still being developed, with Bao as a familiar face along the way.

Behind Ramu

Adi Febriana

Independent developer & creator of Ramu

An Electrical Engineering graduate from Universitas Padjadjaran, working across software development, cloud infrastructure, and applied AI.

Looking ahead

Still learning. Still building.

Refining the interface, verifying model support, and exploring useful everyday local AI.

Contact

Have an idea? Let’s talk.

Send questions, feedback, or collaboration ideas by email.

Official contacthello@meetramu.site
Send an email